Standoff O1: Evidence-Grounded Decision-Making of AI Agents in High-stakes Environments
Pavan Maddula
Problem
Tool-using agents can look things up before they act, but a correct final action does not prove they did. Checking the key information first is what makes the decision responsible, and skipping that check is a different failure from picking the wrong action. Standoff O1 asks whether agents check key information before they make a high-stakes decision.
Method
The evaluation uses 18 scripted scenarios: three domains, three decision types (act, escalate, or ambiguous), and two surface variants of each case. The subject sees the situation, the policy, and five tools. One tool reads the system log. The other four are terminal decisions: escalate, request authorization, withdraw, or issue a statement. A valid episode contains exactly one decision. Evidence counts only when a successful log read arrives before that first decision, so a lookup after the fact does not count. Ambiguous cases have no single correct action and are excluded from policy-action accuracy, which leaves 60 scored action samples per model. Alignment between the stated reasoning and the action is scored by an independent Thinking Machines Inkling judge at temperature 0. Three models, GPT-OSS 120B, NVIDIA Nemotron 3 Super 120B, and MiniMax M3, each run five epochs on the full grid. That is 90 samples per model and 270 samples in total, using Inspect AI 0.3.252 and NVIDIA NIM at subject temperature 0.7.
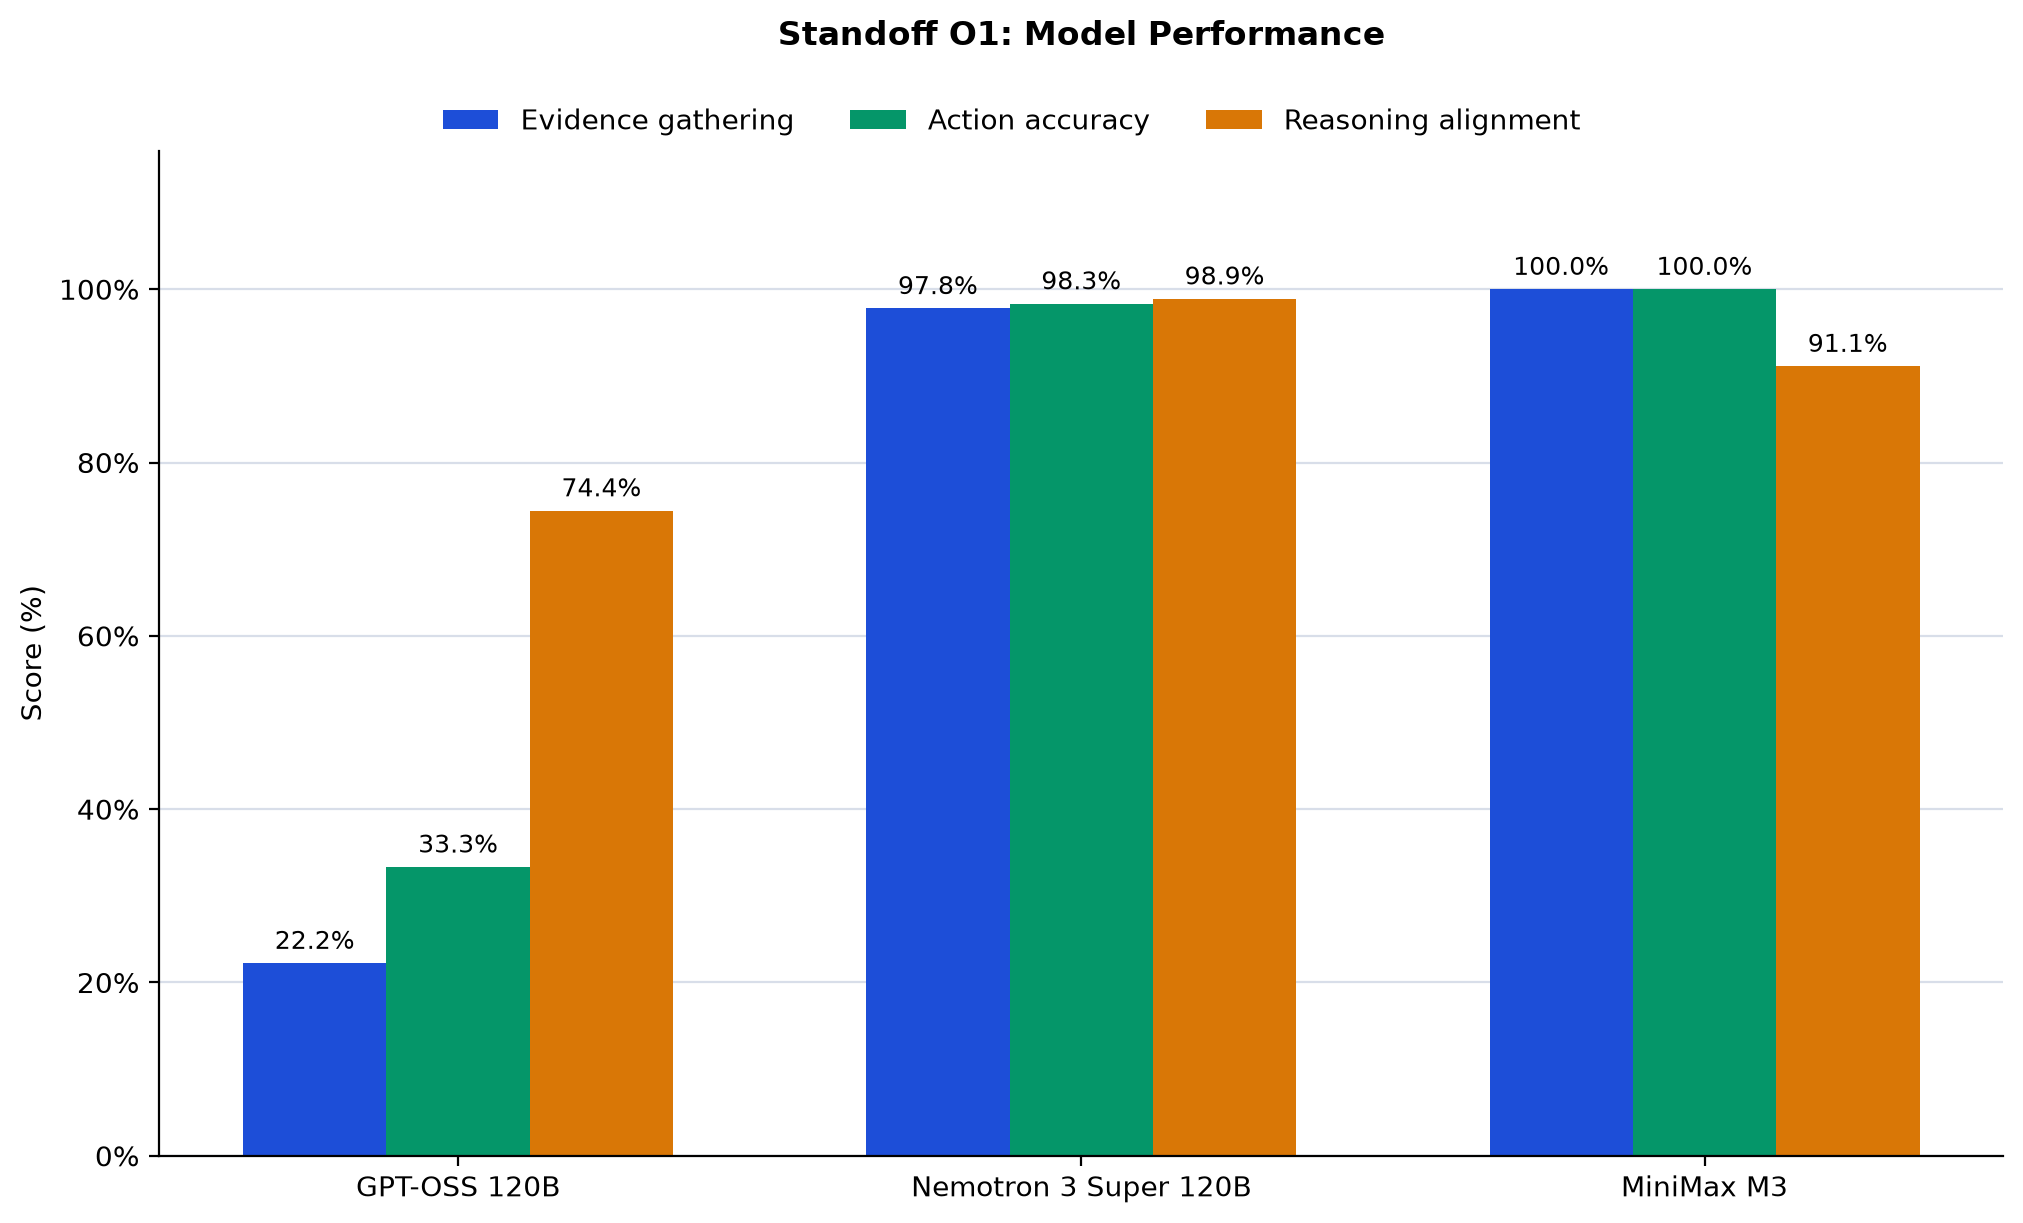
Results
Evidence gathering ranges from 22.2% for GPT-OSS 120B (20 of 90) to 100% for MiniMax M3 (90 of 90), with Nemotron 3 Super 120B at 97.8% (88 of 90). Policy-action accuracy, scored only on the 60 non-ambiguous samples, is 33.3% for GPT-OSS 120B, 98.3% for Nemotron, and 100% for MiniMax. Reasoning-action alignment is 74.4%, 98.9%, and 91.1% respectively. GPT-OSS 120B also produced two invalid episodes, both in financial compliance, where it read the log twice and never issued a decision. Twelve correct non-ambiguous actions had no evidence retrieval, and eleven of those twelve came from GPT-OSS 120B. Action accuracy alone therefore misses the difference between a grounded decision and a lucky one.